Sam’s Story
Proof of concepts are cheap. Production isn’t. Discover why one post-production team replaced rising token bills with a four-GPU rack server capable of running a 70B model entirely on-premises.


The Cloud Bill
Sam runs AI inference for a mid-sized post-production house. Three months into production deployment, the proof of concept that had wowed the team was getting expensive. Cloud inference was getting costly and his budget was taking a hit.
At sustained load, your bill grows faster than your usage does. Every time Sam scaled up inference volume, added users, or extended the model to a new part of the pipeline, the token cost stacked. Cloud pricing bills per inference and his production workload ran all day.
A bigger cloud model was an option. Sam called one of our engineers and put the compute in the rack instead.
The VRAM Problem
Sam’s brief was specific. A 70B parameter model, client data that needed to stay on-site, with GDPR requirements to consider, and two rack units of space.
A 70B model needs more than 140GB of VRAM. A single RTX PRO 6000 Blackwell card delivers 96GB. Two standard cards give you the VRAM ceiling while the inter-GPU bandwidth to run inference across them efficiently requires a different configuration. Four cards in a chassis engineered for the thermals, the bandwidth was the answer.
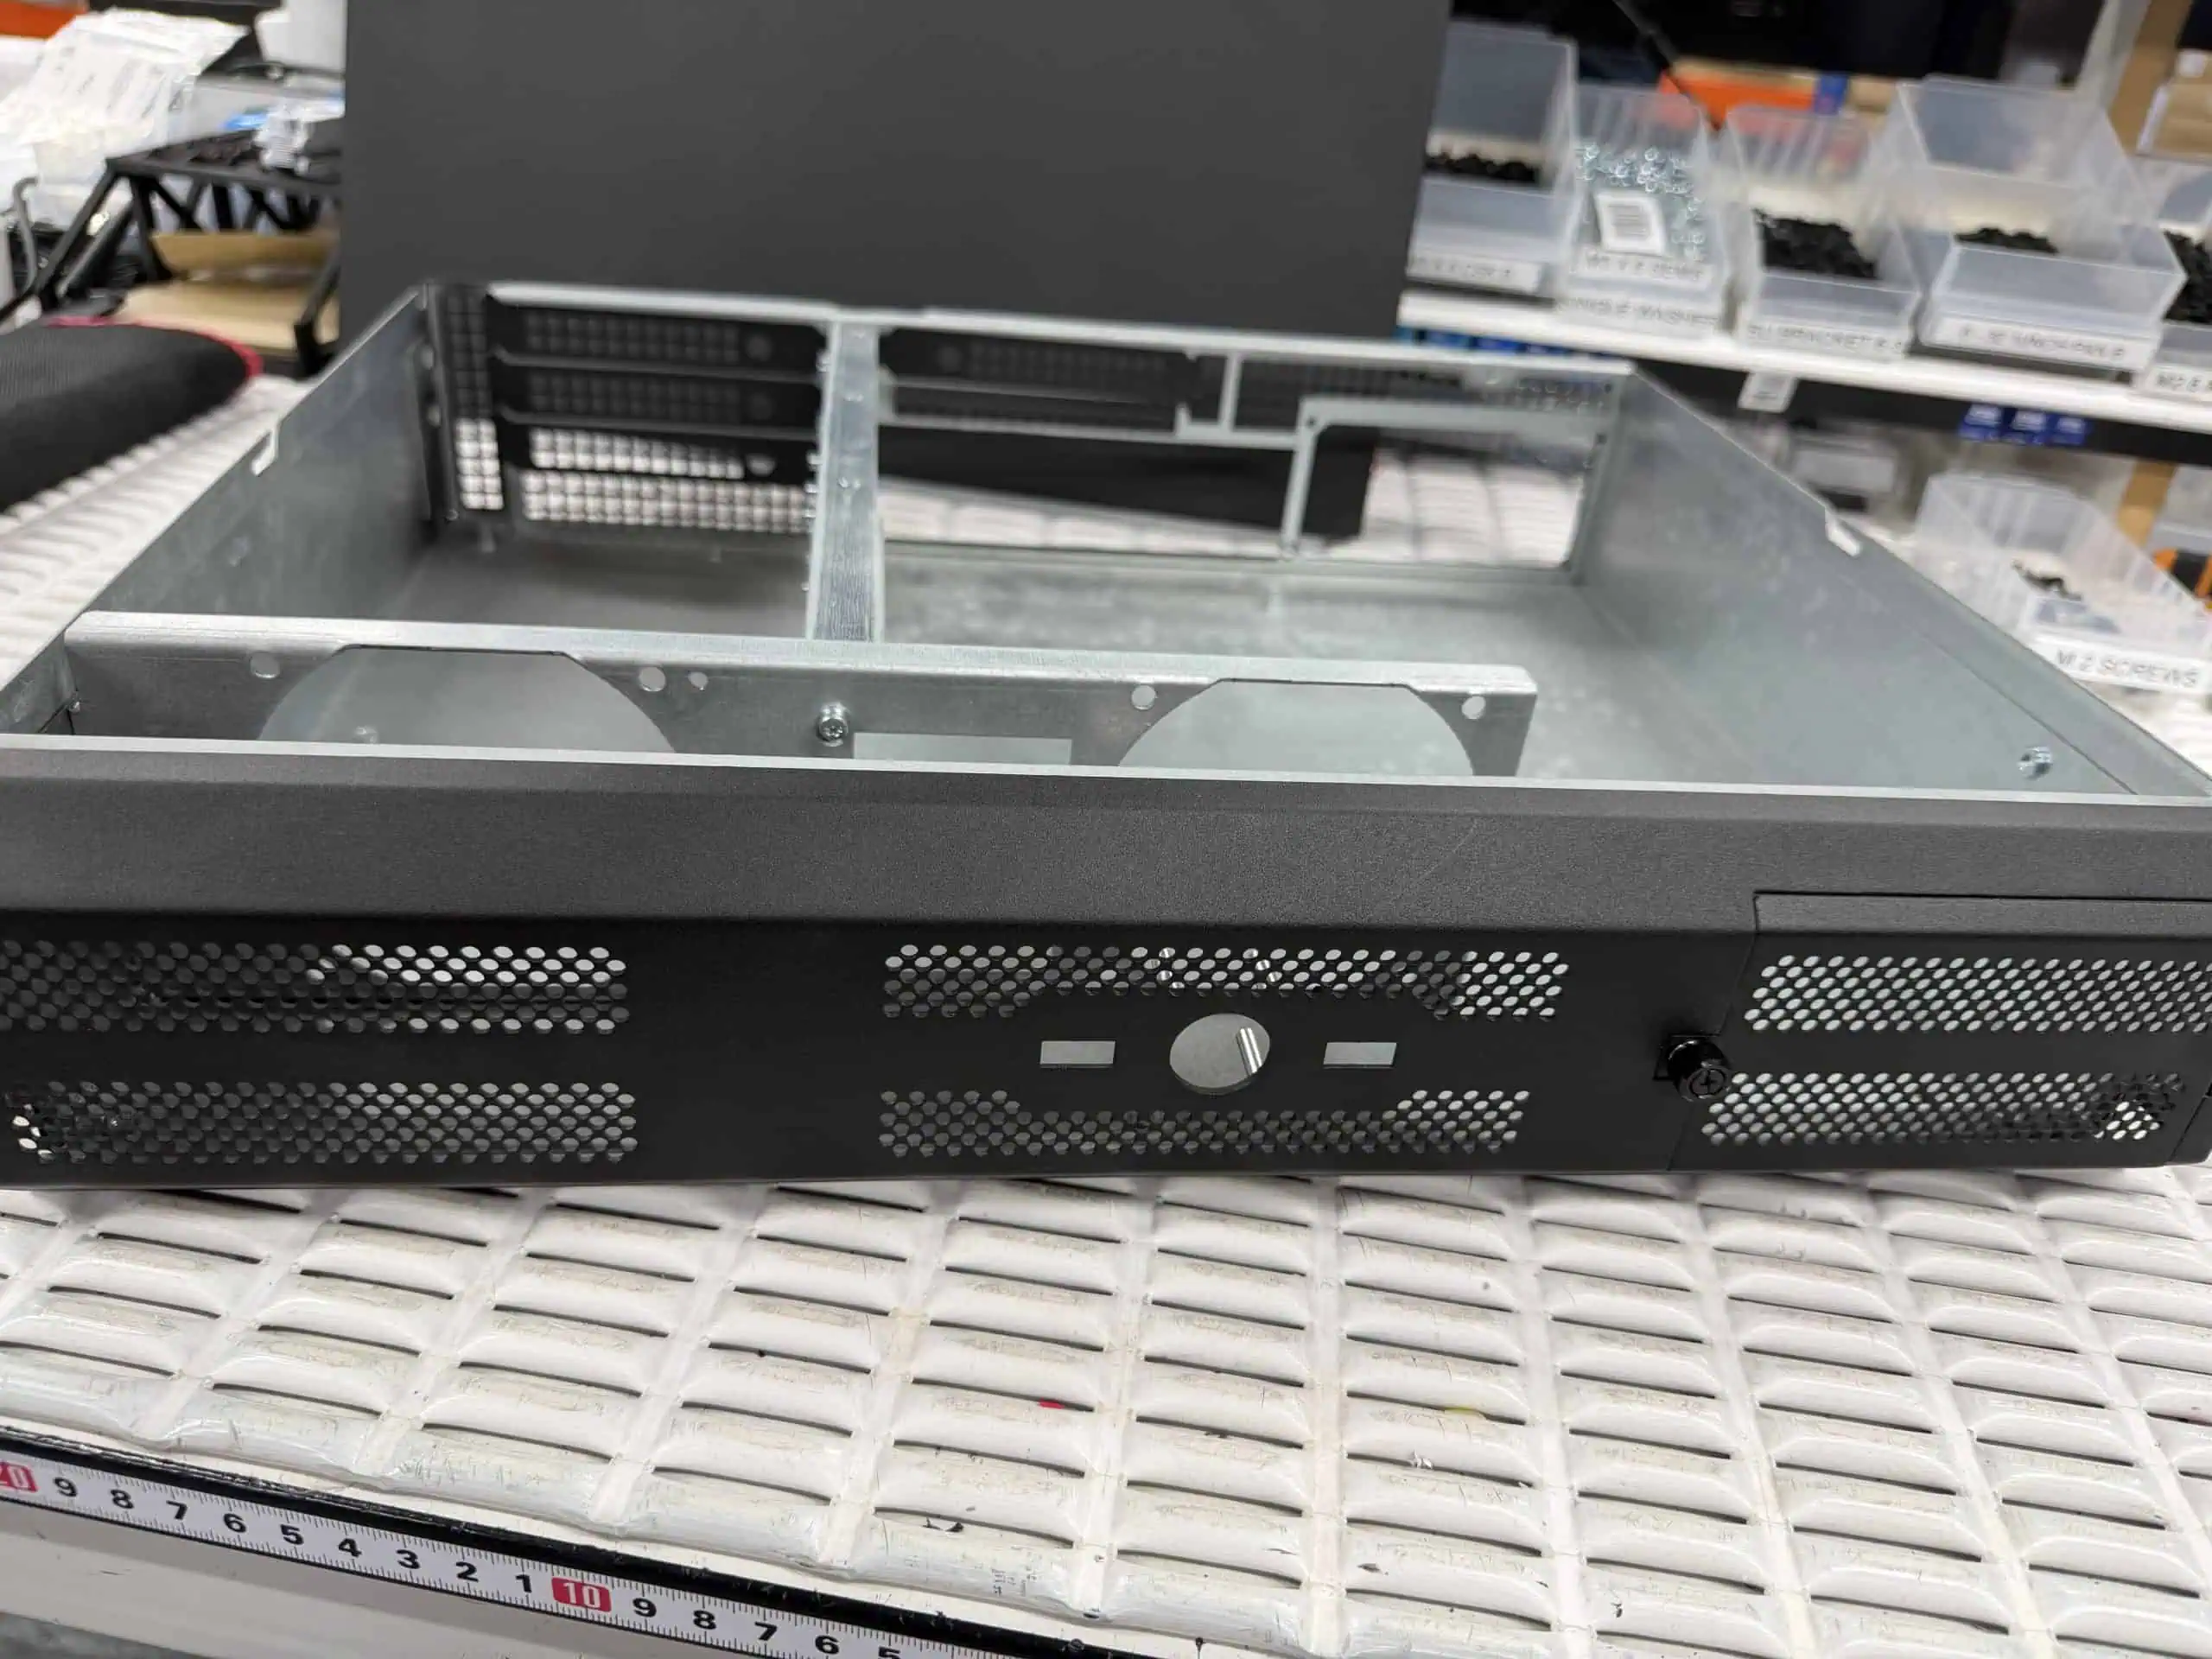
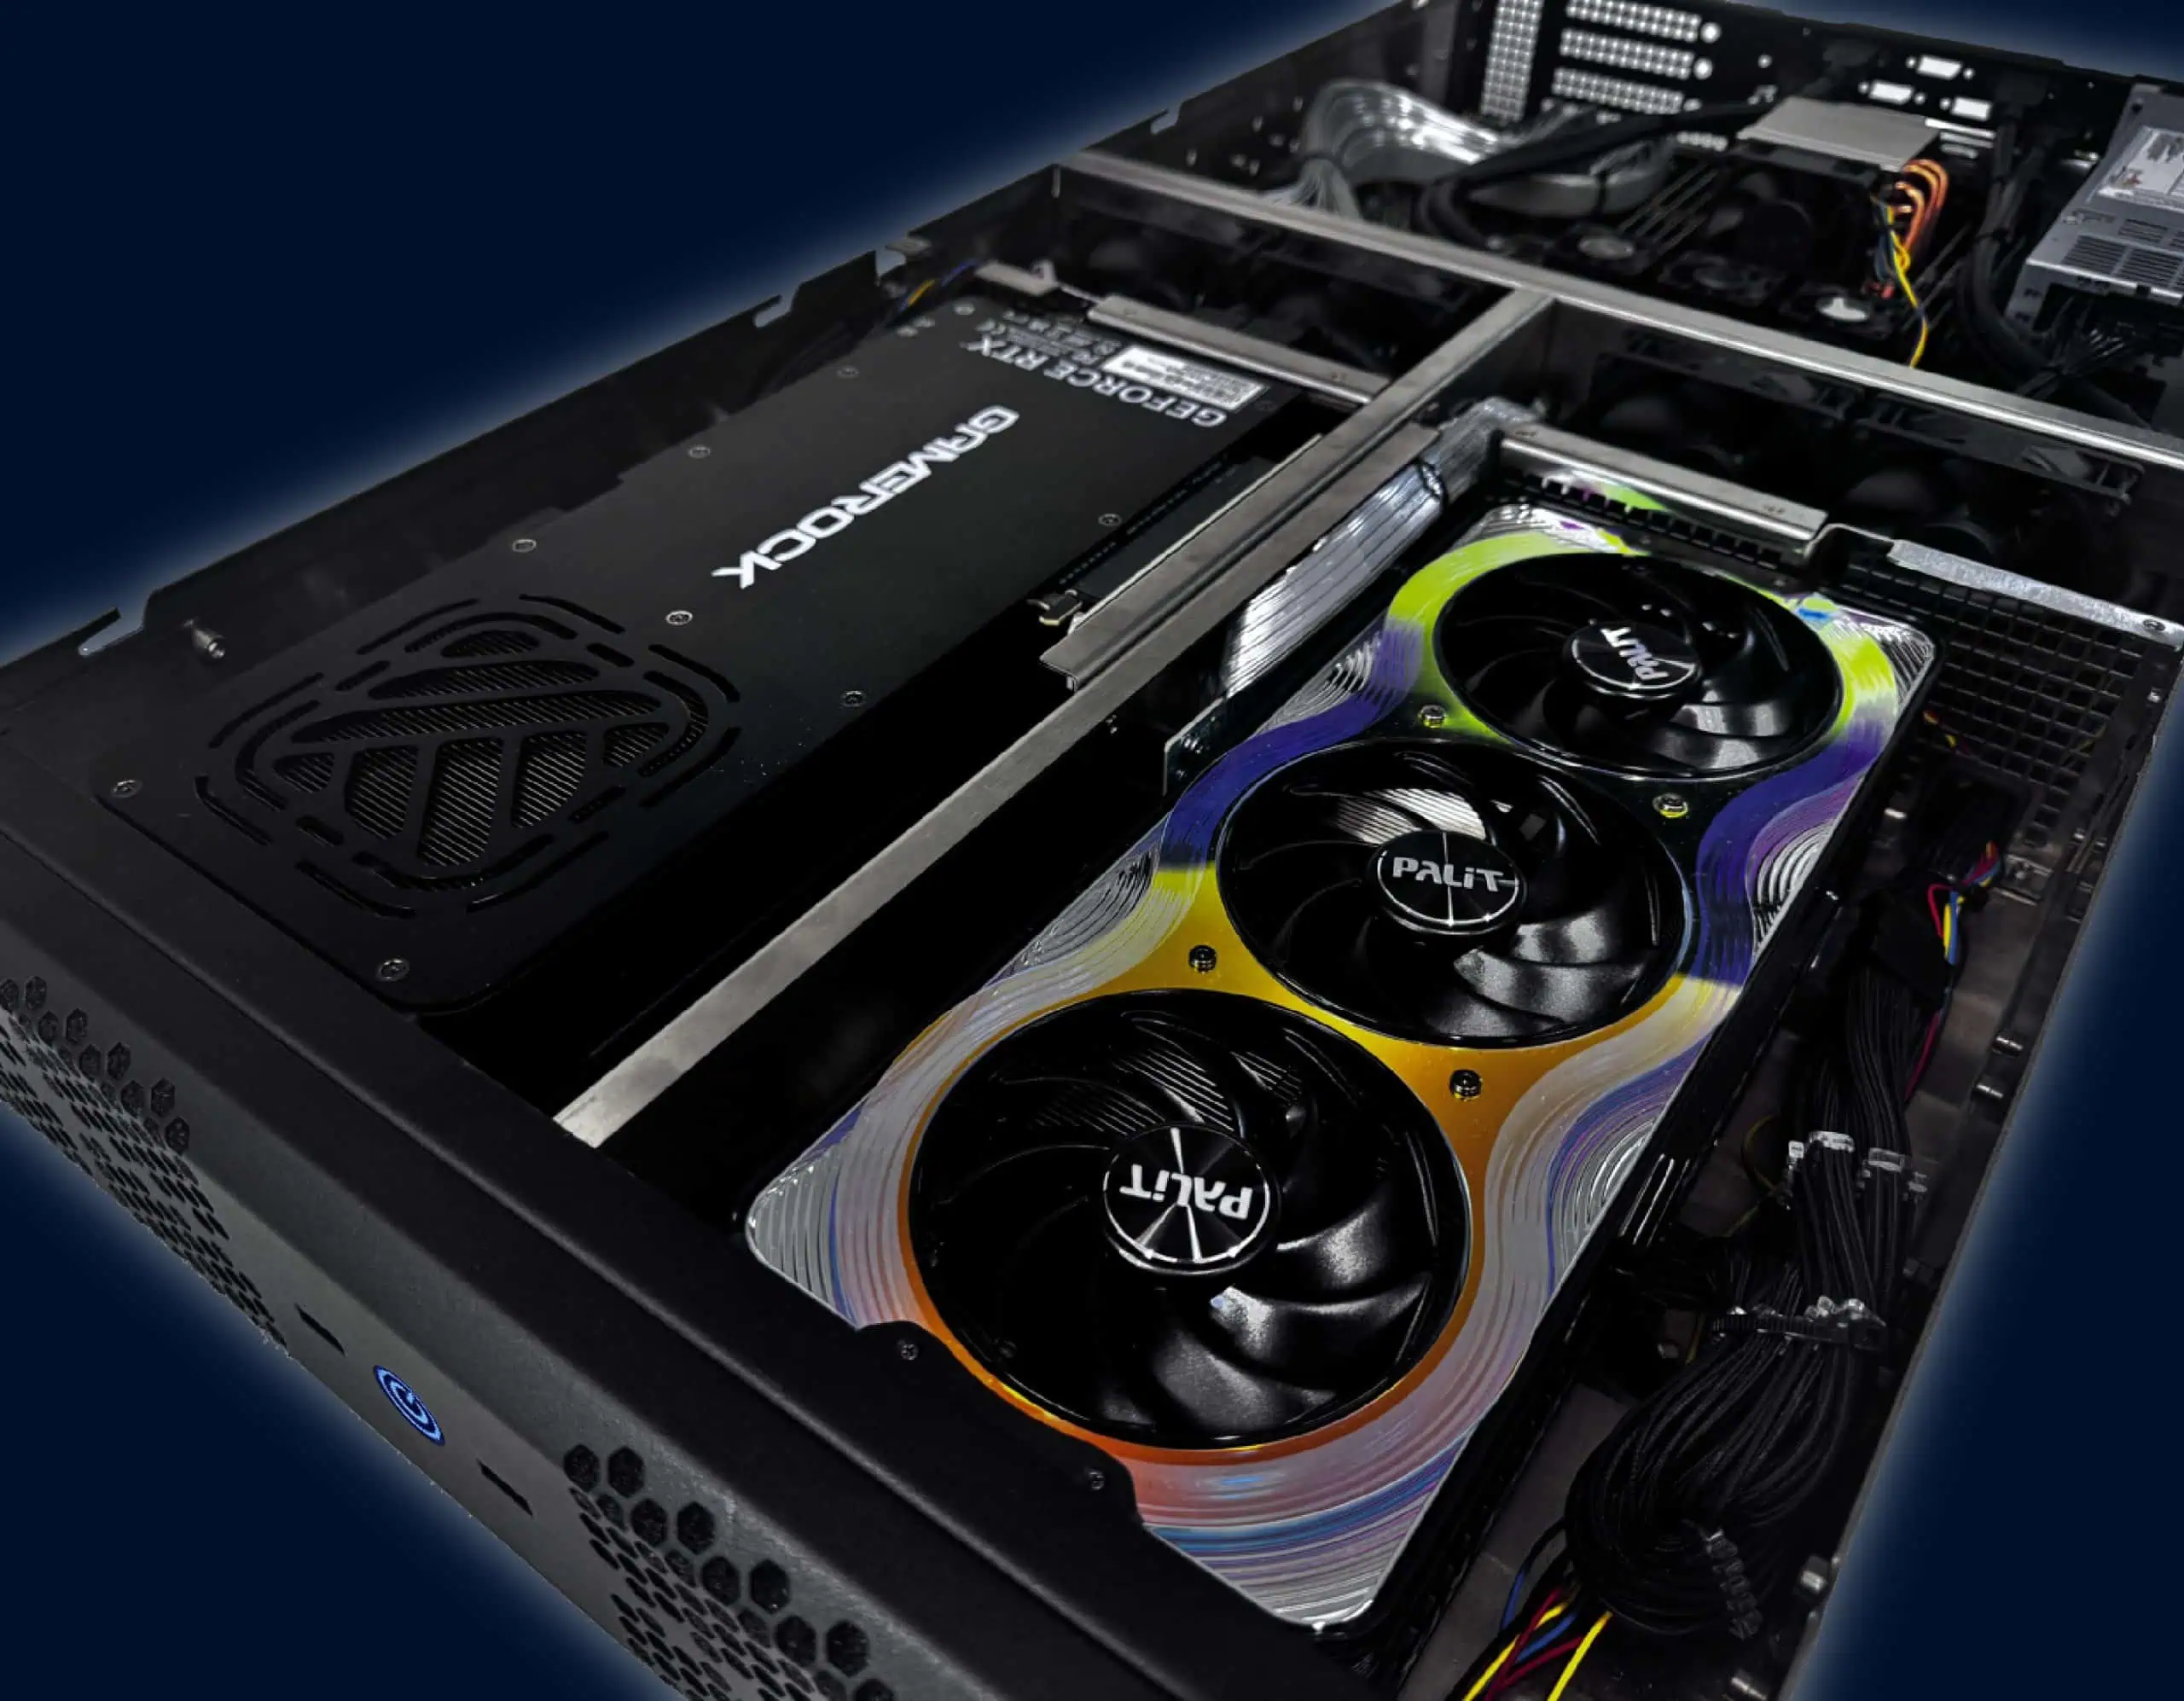
The 2U Q-Power puts four RTX PRO 6000 Blackwell cards in a 2U 890mm chassis. 384GB ECC VRAM in two rack units, enough to load Sam’s 70B model fully into VRAM and run inference without offloading. The chassis is built to handle four cards running flat out. The Q-Power is engineered around sustained workloads, with configurations tested before they leave Hampshire.
Sam had two rack units. The 2U Q-Power filled them.
For Sam’s 70B model requirement, we configured the quad NVIDIA RTX PRO 6000 Blackwell option, four cards, 384GB ECC VRAM, in the same 2U 890mm chassis. The full model loads into VRAM and inference runs at sub-40ms latency with the data staying on the network throughout.
The Impact
Sam’s team moved production inference on-premises. The per-token cost dropped by a factor that means the hardware will pay for itself within a year. The latency dropped from 1.5 seconds on a cloud round-trip to under 40ms on-site.
The cloud contract is still in use, experimental workloads still go there. The work that runs every day, processes volume and was driving costs runs on hardware G2 built all in a rack Sam’s team controls.
View more on the 2U Q-Power, or view the product page here.
G2 Digital builds GPU-dense rack servers for teams running serious workloads on-premises. Arrive with a partial spec. Leave with a plan.
Talk to an engineer →
 Need a quick answer right now? Chat with us live using the icon at the bottom right of your screen